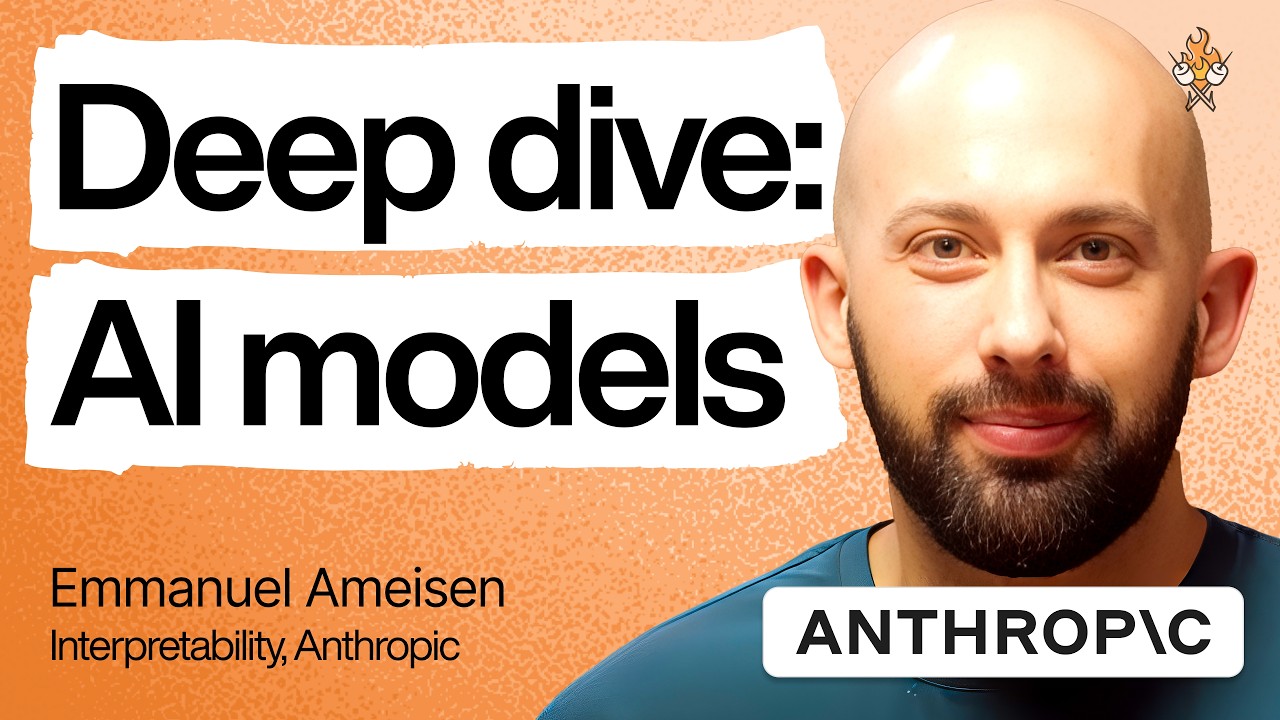
Inside the black box of AI: How AI models actually think | Emmanuel Ameisen (Anthropic)

About this episode
From the show’s notesEmmanuel Ameisen is an interpretability researcher at Anthropic, where he looks inside LLMs like Claude to understand how they think. Before joining Anthropic, he spent years in applied ML at Stripe and Insight, and is the author of Building Machine Learning Powered Applications. His research has produced some of the most striking findings in the field: that models form general representations of concepts, plan many tokens ahead without stating those plans explicitly, and may exhibit something structurally similar to the distinction between conscious and unconscious processing in humans.
*We discuss:* 1. Why the “next-token predictor” framing undersells how models actually plan and think 2. Why anthropomorphizing AI can actually be the right approach 3. Why models are “grown,” not built 4. What the “J space” reveals about model self-awareness 5. The smooth scaling curve behind what look like sudden capability jumps 6. How interpretability connects to AI alignment and safety
Read the show’s notes in full
*Brought to you by:*
WorkOS—Make your app enterprise-ready, with SSO, SCIM, RBAC, and more: workos.com/lenny
DX—Engineering intelligence for the AI era:
getdx.com
*Episode transcript:* lennysnewsletter.com/p/a-mind-e…
*Archive of all Lenny's Podcast transcripts:*
dropbox.com/scl/fo/yxi4s2w998p1…
*Highlights:*


 amazon.com/dp/0063286343